DAILY DRIVERS
Building reliable software.
Making AI useful.
I work on backend systems, AI applications, and the engineering that makes them dependable.
Software & AI Engineer
MahaboobAshraf
NOWSoftware & AIHyderabad · India
BUILDINGView workApps, systems, tools
CONTRIBUTINGOpen sourceCode, tests, upstream fixes
REACH OUTStart a conversation
How I work and what I build with
HOW I WORK
High agency, async-first, ships fast
CONNECTED BY DESIGN
From individual parts.
To a working product.
Models, APIs, and data become useful through testing and human judgement.
MY CORNER OF THE INTERNET
Code, research, and conversation.
EXPLORE · CONNECT · SAY HELLO
Selected work.
Systems built to make complex engineering useful, inspectable, and dependable.
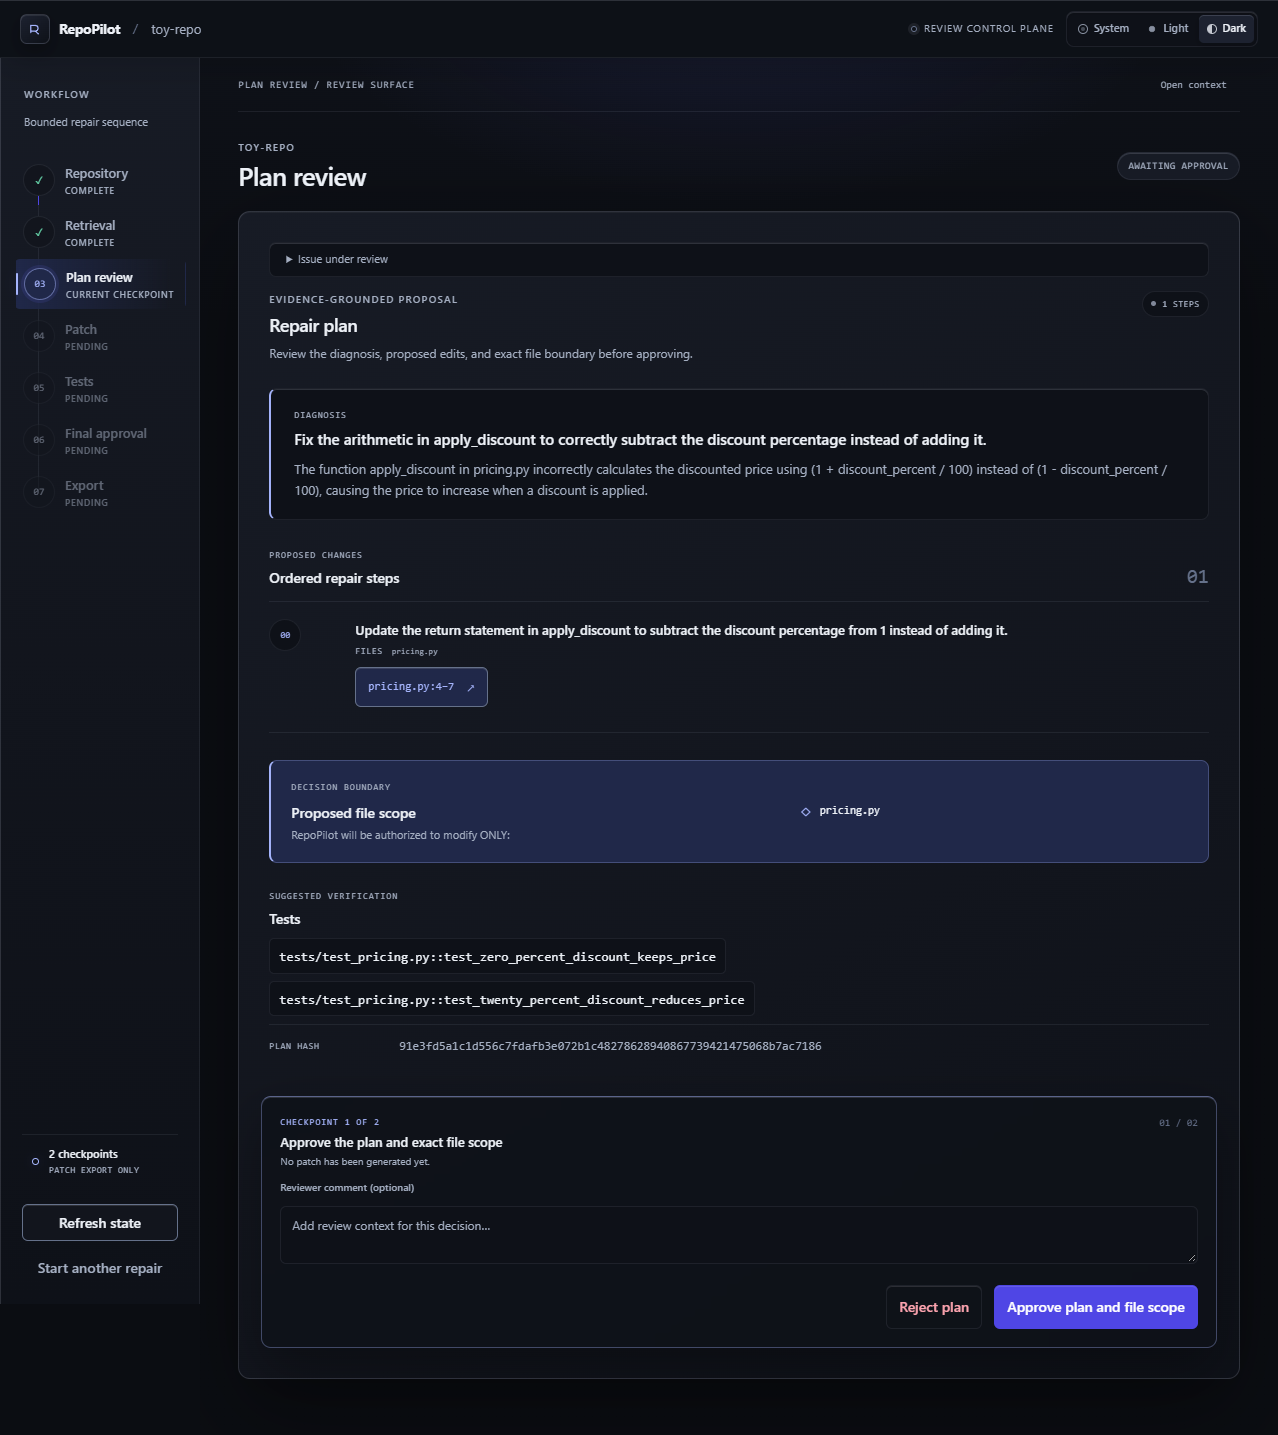
RepoPilot
LOCAL-FIRST AGENTRepoPilot repairs Python repositories with evidence and human review. It tests bounded changes and exports only an approved patch.
- Finds relevant code with hybrid search
- Human approval before changes and export
- Tests proposed fixes in isolated Docker runs
- Exports the exact patch you reviewed
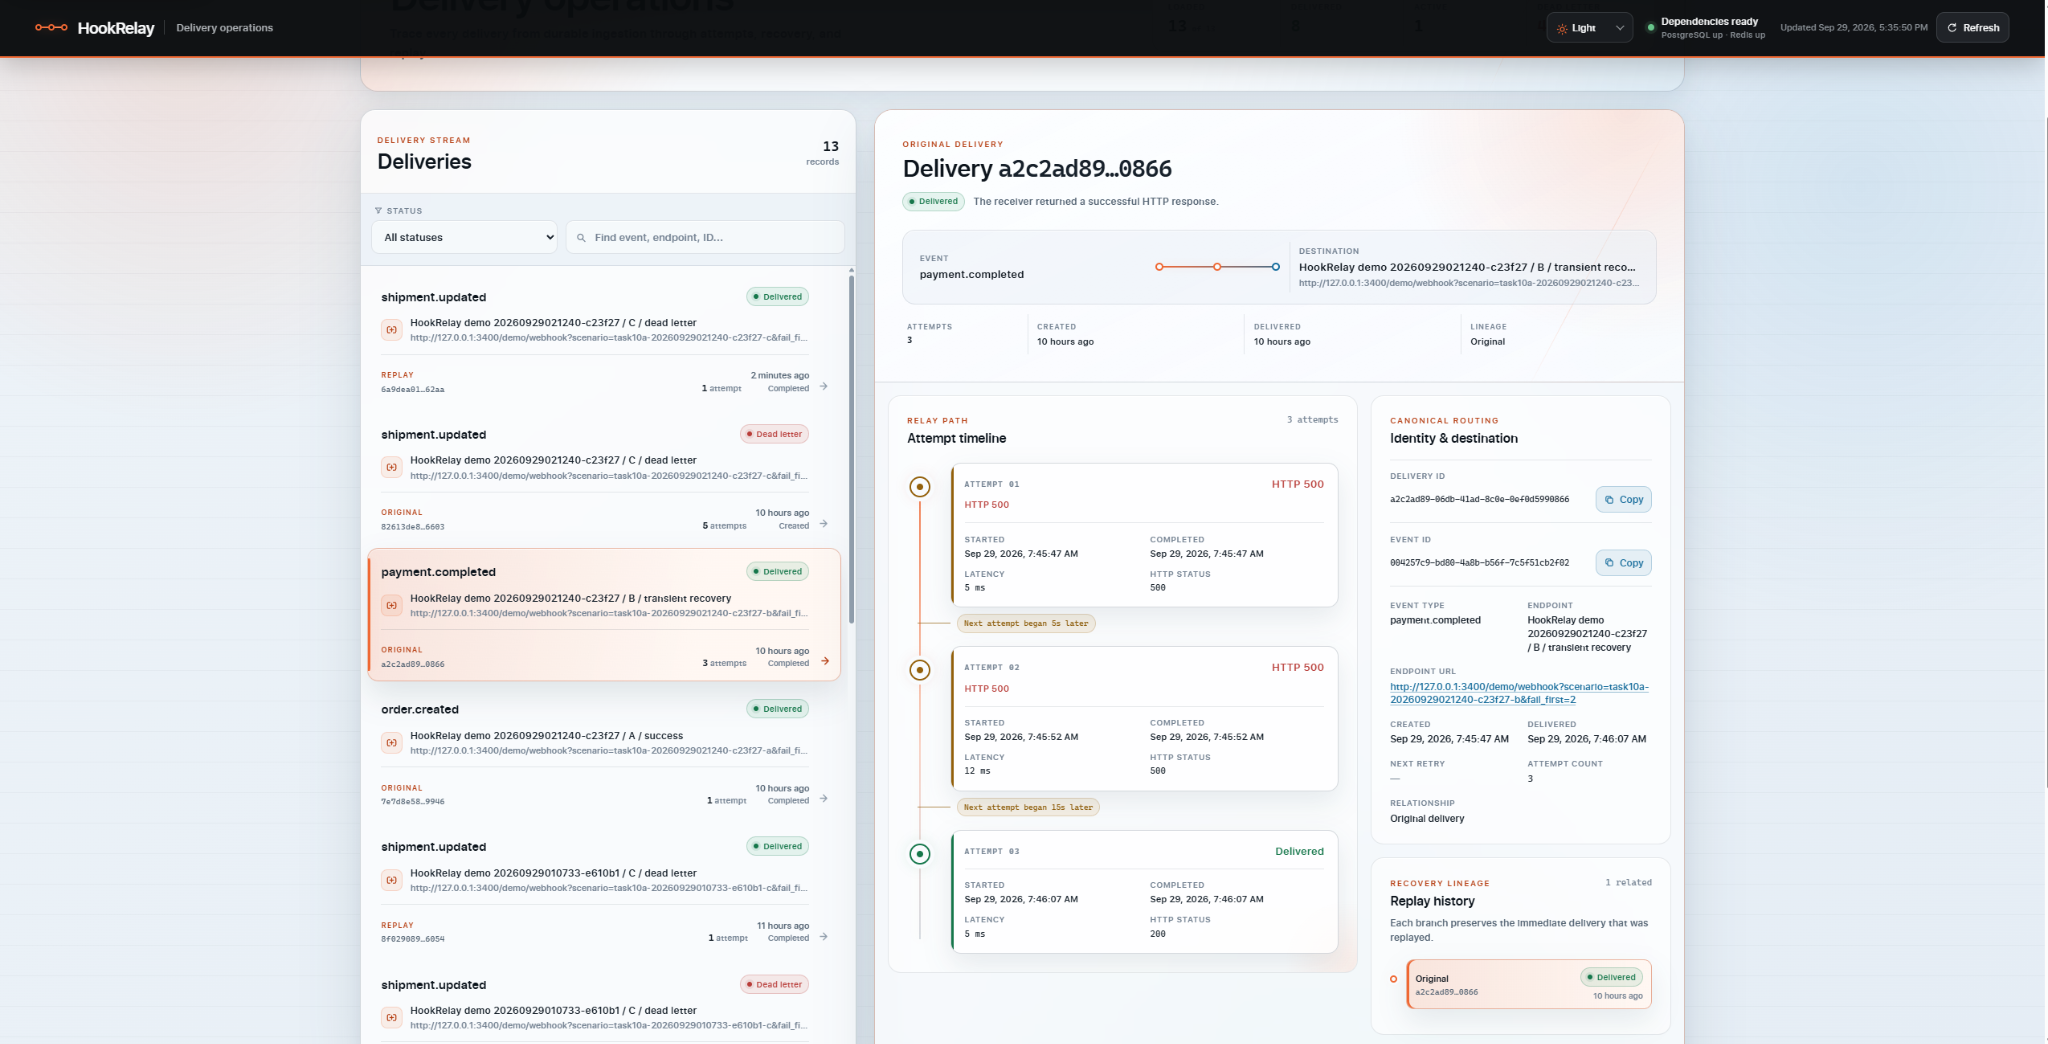
HookRelay
WEBHOOK INFRASTRUCTUREHookRelay traces outbound webhooks through failure, retry, and replay. Signed delivery attempts stay inspectable, even when a receiver fails.
- Prevents duplicate event acceptance
- Signs outgoing webhooks with HMAC
- Retries temporary failures automatically
- Replays failed deliveries with linked history
Amana
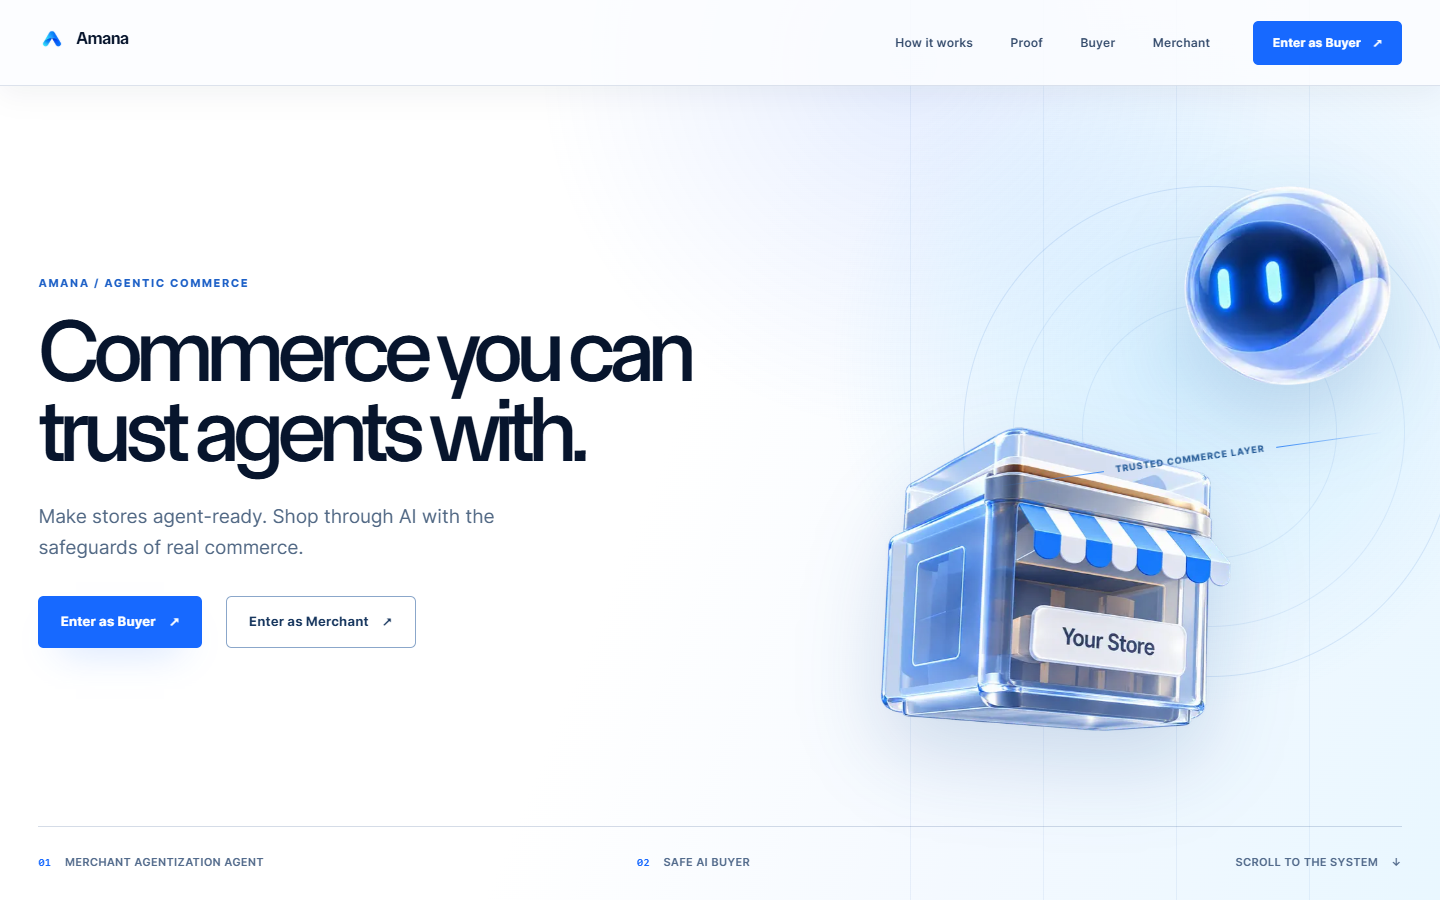
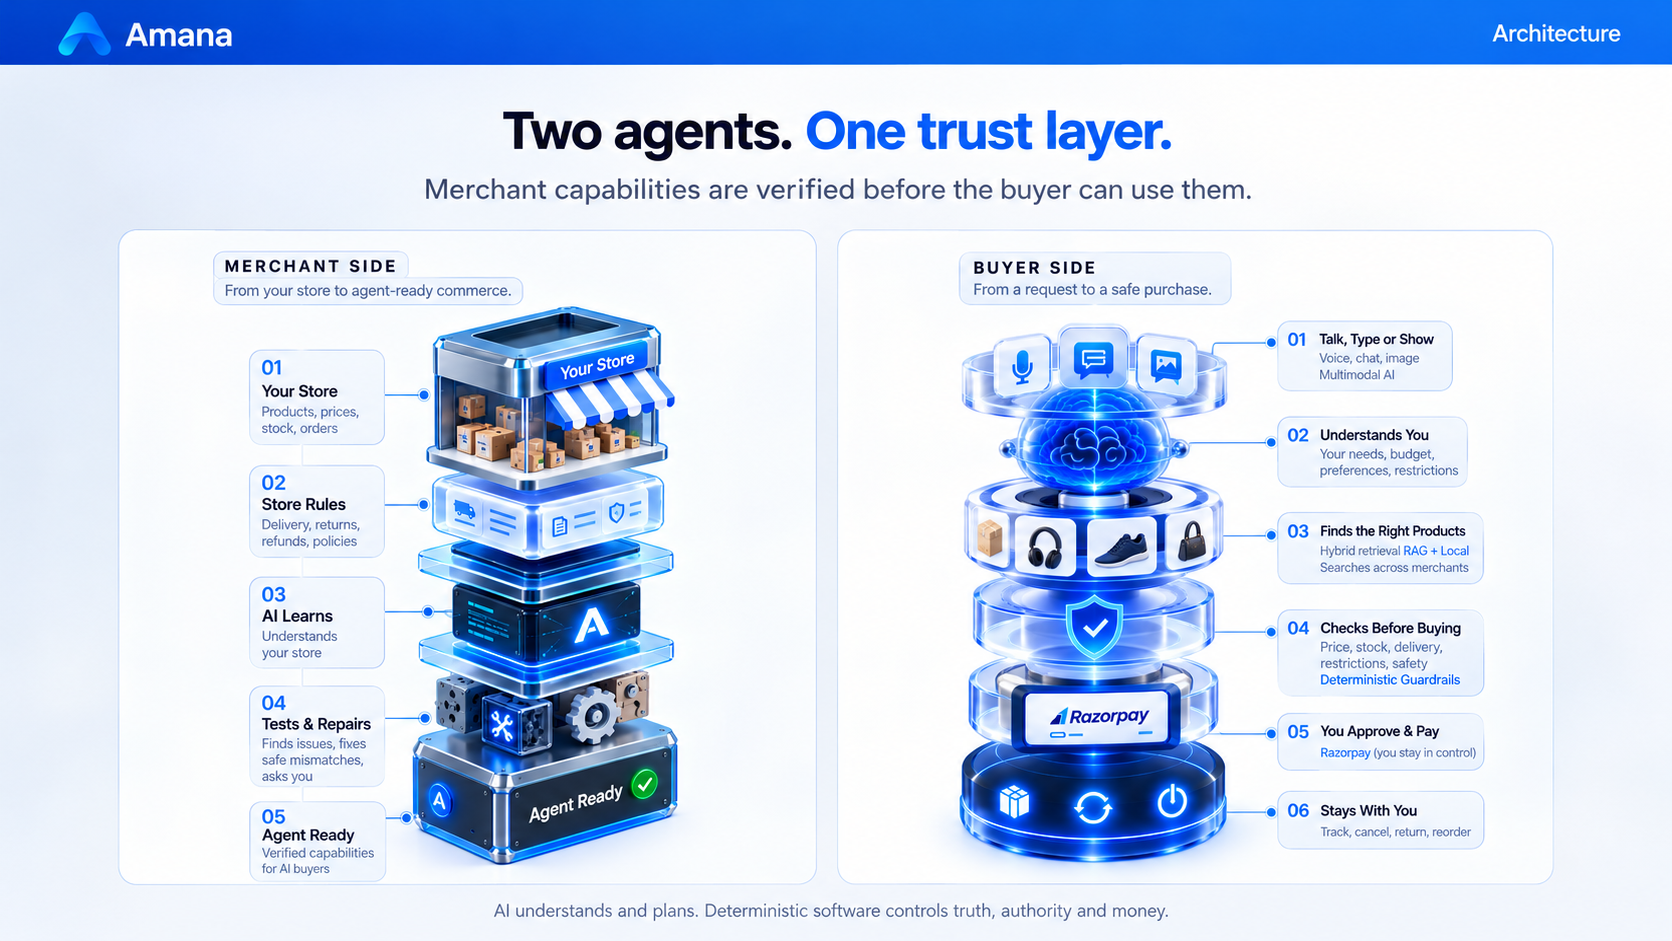
COMMERCE TRUST LAYERAmana makes merchant systems usable by AI buyers while keeping financial decisions under deterministic control. Purchases require an explicit, immutable proposal.
- Tests merchant capabilities before use
- AI interprets intent and proposes API mappings
- Explicit approval binds each purchase proposal
- Explore buyer and merchant demos in test mode
BEYOND MY OWN PROJECTS
Open source contributions
Agenta
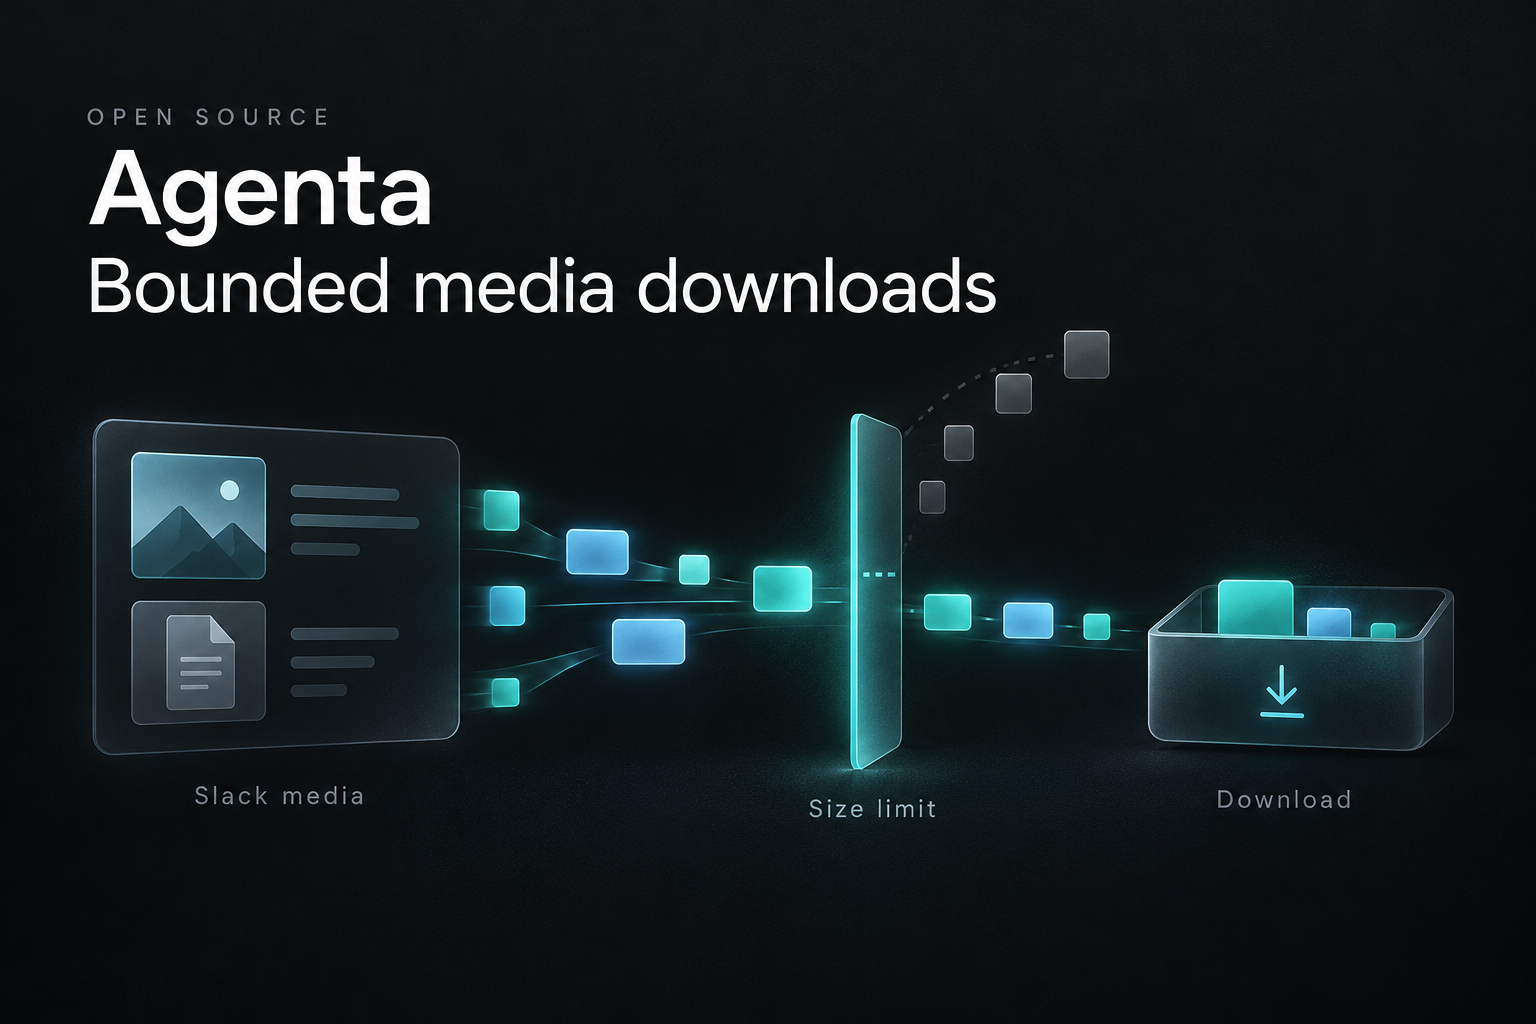
Bounding Slack media downloads
Implemented limits on Slack media downloads to prevent oversized attachments from consuming excessive resources.
Pydantic · Logfire
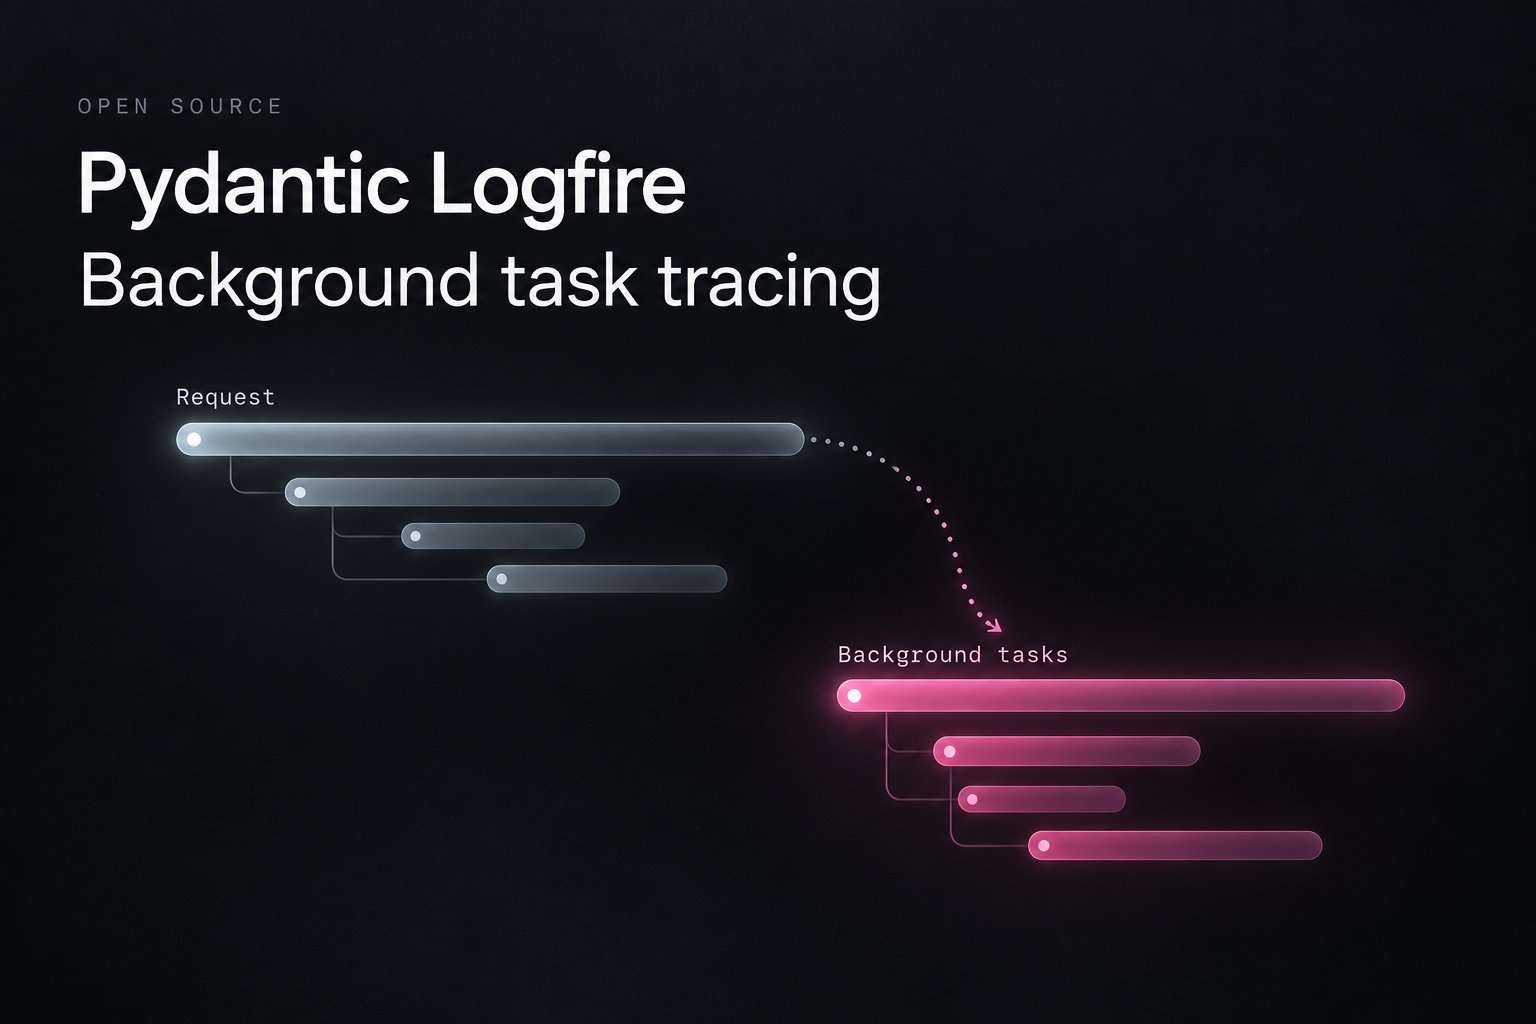
Tracing FastAPI background tasks
Implemented separate, linked traces for background task batches so they can be sampled independently of requests. Added regression tests and documentation.
DSPy
Cleaning up deployment snapshots
Proposed a fix for deployment snapshot cleanup, with the implementation available for review in the pull request.
KNOW ABOUT ME
Curious by nature.
Engineer by practice.
I’m Mahaboob Ashraf, a software engineer based in India. I build AI applications and backend systems, with a focus on how models, APIs, and data come together in a working product.
My experience includes computer vision research at iHub-Data, IIIT Hyderabad, and machine learning for antibody manufacturing at Drugparadigm. Alongside my projects, I contribute to open source, working through real codebases, tests, and maintainer feedback.
I’m looking to work with small teams building useful AI products - through contracts, internships, or remote engineering roles.
RESEARCH & EXPERIENCE
Applied AI.
Real-world problems.
2025 – Present
– Present
 Drugparadigm Hyderabad
AI Research Intern
- Developed and evaluated an initial machine-learning approach to predict bispecific-antibody manufacturing yield from sequence data. Limited labeled training data and very low, inconsistent evaluation performance prevented reliable predictions, motivating a shift toward a more measurable ML problem.
- Helped redefine the research objective as sequence-pair matching and ranking: predicting which two protein chains naturally belong together. This enabled large-scale supervised learning and more rigorous comparisons against established models.
- Engineered large-scale Python data pipelines to preprocess, annotate, clean, and validate approximately 3.75 million paired sequences. Implemented metadata enrichment, dataset filtering, negative-sample construction, and data-integrity checks to support reproducible training and evaluation.
- Built and optimized PyTorch training and evaluation workflows, using pretrained sequence embeddings and reusable feature caches to process millions of examples efficiently. Experimented with classification, ranking objectives, and negative-sampling strategies to improve model performance.
- Conducted extensive model evaluation, statistical benchmarking, and error analysis, examining dataset biases, sampling effects, and unreliable labels. On a matched held-out benchmark, achieved 0.798 ROC-AUC (κ) and 0.823 (λ) versus 0.750 and 0.783 for ImmunoMatch, respectively.
- Benchmarked against p-AbNatiV2 on identical held-out candidate sets, achieving 79.66% vs 74.49% accuracy in 1-vs-1 matching and 20.72% vs 8.56% Top-1 retrieval accuracy in 1-vs-50 ranking (κ), while identifying limitations requiring further research.
STACK
 Python
- PyTorch
- NumPy
- pandas
- Protein Sequence Embeddings
- Large-Scale Data Processing
- Ranking Models
- ML Evaluation
AI Research Intern
- Built a UAV-detection pipeline, fine-tuning YOLOv8m on a custom dataset of 1,350+ annotated images.
- Achieved 96.7% mAP@50, 94.7% precision, and 93.2% recall on 272 validation images containing 287 drone instances.
- Applied CLAHE and median-blur preprocessing alongside AdamW optimizer tuning to address low-contrast imagery and visually cluttered scenes.
- Evaluated detection performance using confusion matrices, precision–recall curves, F1-confidence curves, and annotated predictions.
STACK
- Python
- YOLOv8
- Ultralytics
- OpenCV
- Matplotlib
- Google Colab
LET’S CONNECT
LET’S TALK ABOUTWHAT’S NEXT.
I’m open to contracts, internships, and remote engineering roles.
STRAIGHT TO MY INBOX